What is Robots.txt & How it Guides Search Engines?
Robots.txt
A website's robots.txt file tells search engine crawlers which pages or directories they can access. This ensures they don't waste time crawling unnecessary or private sections of your site.



What is Robots.txt, and What is its Basic Purpose?
A robots.txt file is used to communicate to web crawlers like Googlebot and Bingbot as to which sections of a website they are permitted to visit and which sections they should avoid visiting. One of the first files that web crawlers examine is this one, and it is stored in the primary folder of your website.
How Robots.txt Guides Search Engines?
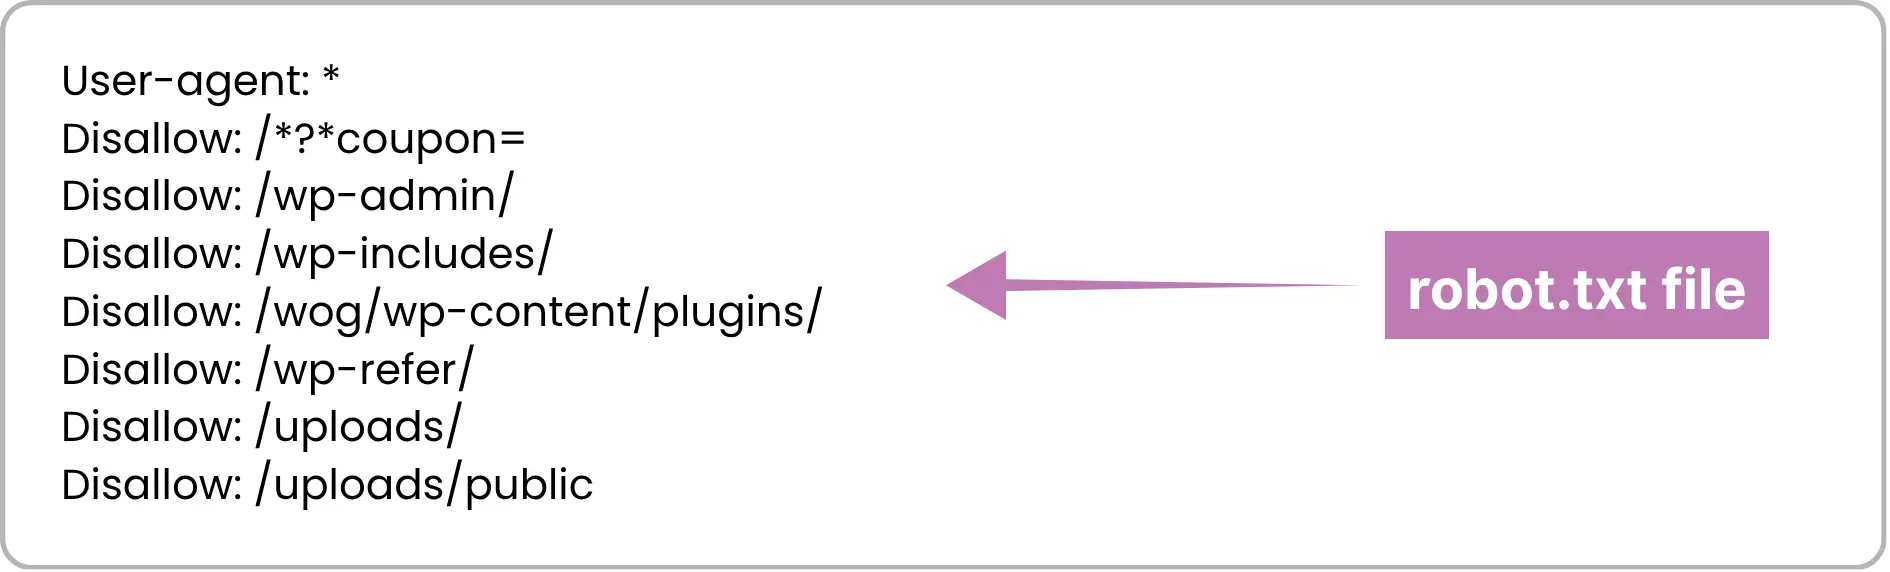
When a search engine gets to your site, it will first look at the robots.txt file before it starts to crawl.
User-agent: The User-agent line specifies which crawler the rule is intended for. It can target specific bots like Googlebot or Bingbot, or use an asterisk (*) to apply the rule to all bots.
Disallow: Keeps bots out of named folders or pages such as /admin/ or /checkout/.
Allow: Lets bots go into places that could be closed off otherwise.
If there is no robots.txt file, the crawlers think they can look at all parts of the site.

Difference Between Robots.txt & Meta Robots Tags
Aspect | Robots.txt | Meta Robots Tag |
|---|---|---|
Control Level | Directory/URL level | Individual page level |
Primary Purpose | Controls crawling | Controls crawling and indexing |
Blocking Access | Prevents bots from accessing content | Doesn’t block access |
Indexing Control | No indexing control | Can stop pages from being indexed |
Requires Crawling | No, applied before crawling | Yes, must be crawled first |
Bot Behavior | Can be ignored by bad bots | Recognized by most crawlers once accessed |
How Search Engines Interpret Robots.txt: Crawling vs Indexing?
Search engines perform two main tasks:
Crawling: This is when search engines go to web pages. They find and follow links on these pages to look for more pages.
Indexing: In this step, search engines keep those pages and check what is on them. They use this information to show the right pages in search results.
Robots.txt is used to control which pages bots visit. It stops bots from going to some pages. It does not delete or take away things that have already been added to search engines.
Step-by-Step Guide to Creating and Implementing robots.txt
1. Create the file: Open a text editor and name it robots.txt.
2. Add rules: Use User-agent, Disallow, and Allow lines. These help you say what parts bots can see on your site.
3. Save properly: Save the file as UTF-8.
4. Upload: Put the file in the root folder of your website (for example, yourdomain.com/robots.txt).
5. Test: Go to Google Search Console and use the robots.txt Tester. This lets you find any problems right away.

Common Robots.txt Errors and How to Fix Them ?
Wrong location: Always put it in the site’s main folder.
Overusing wildcards: If you use * the wrong way, you can block large parts by mistake.
Using “noindex” in robots.txt: Google does not support this now—use meta tags instead.
Blocking CSS or JS: Do not block important files, or it can hurt how the site shows up in search.
Incorrect slashes (/): Make sure paths to folders are correct.
No testing: Always check your file after you update it so you do not get SEO problems.
Robots.txt & AI-Driven Search
Robots.txt is not only used by regular search engines now. It also matters for Artificial Intelligence (AI) tools like ChatGPT, Claude, and Perplexity. These AI crawlers look at the robots.txt file before they read a website.
Letting AI crawlers scan your pages can help your content show up in answers made by AI. This may help more people see it and trust it. If you block these crawlers, then it might be harder for your content to show up when people use AI search. Still, you can keep things private or stop the crawlers from reaching content that is repeated.
Why AI-based crawler's matter?
They put web content in order for AI search.
They care about meaning and do not just use keywords.
They help get new visits from AI platforms.
How Robots.txt Rules Influence AI Crawler Behavior?
AI crawlers look at the robots.txt file to see which pages they are allowed to read. A good robots.txt file helps keep private things safe. It also lets other people find useful content.
How Robots.txt Impacts SEO & Rankings?
Robots.txt helps with SEO. It does not make your pages rank higher on its own. But it helps search engines look at your most important pages by:
Blocking content that is not needed or content that repeats.
Saving crawl budget so search engines use it on work that matters.
Stopping admin or test pages from showing up in search.
Smart robots.txt management helps search engines crawl your site in a better way. This means your SEO can get stronger as time goes on.
When and How to Update Robots.txt?
Update your robots.txt whenever:
You change how your website is set up.
You put in some new pages or add more sections.
You change your SEO plan.
To update:
Open the file with a text editor and make the needed changes.
Put the file in your site’s main folder.
Check it using Google Search Console to make sure it works.
Be sure you are not stopping important pages from being reached.
Ask Google to crawl your site again.
Look at crawl reports often to see how things are going.
Final Thoughts
Think of robots.txt as the gatekeeper of your website. When configured correctly, it helps search engines focus on what matters most, saving crawl budget and improving your chances of ranking higher. In a competitive digital landscape, every detail counts—and robots.txt is one of those details that can make or break your SEO performance. Start optimizing now to ensure your site stands out where it matters.
Frequently Asked Questions (FAQs)
How does robots.txt differ from a sitemap, and why do I need both?
A sitemap is a list of all URLs you want to search engines to index, helping them discover content faster. Robots.txt does the opposite, it tells crawlers which pages do not crawl. Using both ensures that important pages are discoverable while low-value or sensitive content is blocked, optimizing crawl efficiency.
How can robots.txt affect SEO?
Properly configured robots.txt can improve SEO by preventing search engines from crawling low-value or duplicate content, focusing their attention on your most important pages. Incorrect use, however, can block essential pages and harm your site’s visibility.
How often should I update my robots.txt file?
You should review and update your robots.txt file whenever you add new sections to your site, change the structure, or want to block or allow specific content for crawlers. Regular checks help ensure it aligns with your SEO strategy.
What does “Disallow” mean in robots.txt?
The “Disallow” directive tells search engine bots not to crawl specific pages or directories on your website. For example, Disallow: /private/ prevents crawlers from accessing the /private/ folder.
Does robots.txt prevent pages from appearing in Google search results?
No. Robots.txt prevents crawling but does not guarantee that pages won’t appear in search results. Pages may still appear if other sites link to them. To prevent indexing, you should use a noindex meta tag.
How does robots.txt affect crawl budget for large websites?
Crawl budget is the number of pages search engines crawl on a site over a period of time. Blocking unimportant or duplicate pages ensures crawlers focus on high-value content, improving indexing speed and enhancing SEO efficiency, especially for large sites.
What are the most common mistakes to avoid when using robots.txt?
Placing it in the wrong folder
Blocking critical pages or assets (CSS/JS)
Overusing wildcards incorrectly
Using noindex in robots.txt (deprecated)
Forgetting to test after updates


4.9/5 Ratings!

Share this article