What Is a Web Crawler? How Do Search Engines Rank Websites?
Web Crawler
The Web Crawler is a robot that gets information from the internet and stores it in an index. This bot's main goal is to learn about all the different websites out there.


What is a Web Crawler?
A web crawler (also called a spider or bot) is a software program that browses websites automatically and reads their pages.
Think of a librarian going through a gigantic library where new books are continuously being added every second. The librarian reads each book, writes down what it's about, and takes notes so others can find the proper one quickly later. That's basically what a crawler does but on websites, not on books.
Search engines like Google and Bing use these crawlers to discover, read, and classify the information available on the internet.

How Do Web Crawlers Work?
Let's take it step by step. Crawlers work in a simple loop:
They begin with a set of sites to go to. These may be big popular sites or pages submitted by people.
They go to one page, scan all the text, images, and code.
They look for links on that page (such as a menu or article links).
They click on those links and do the same thing on the new pages.
They just keep doing it repeatedly like a speedy, constant explorer.
Real-life Example:
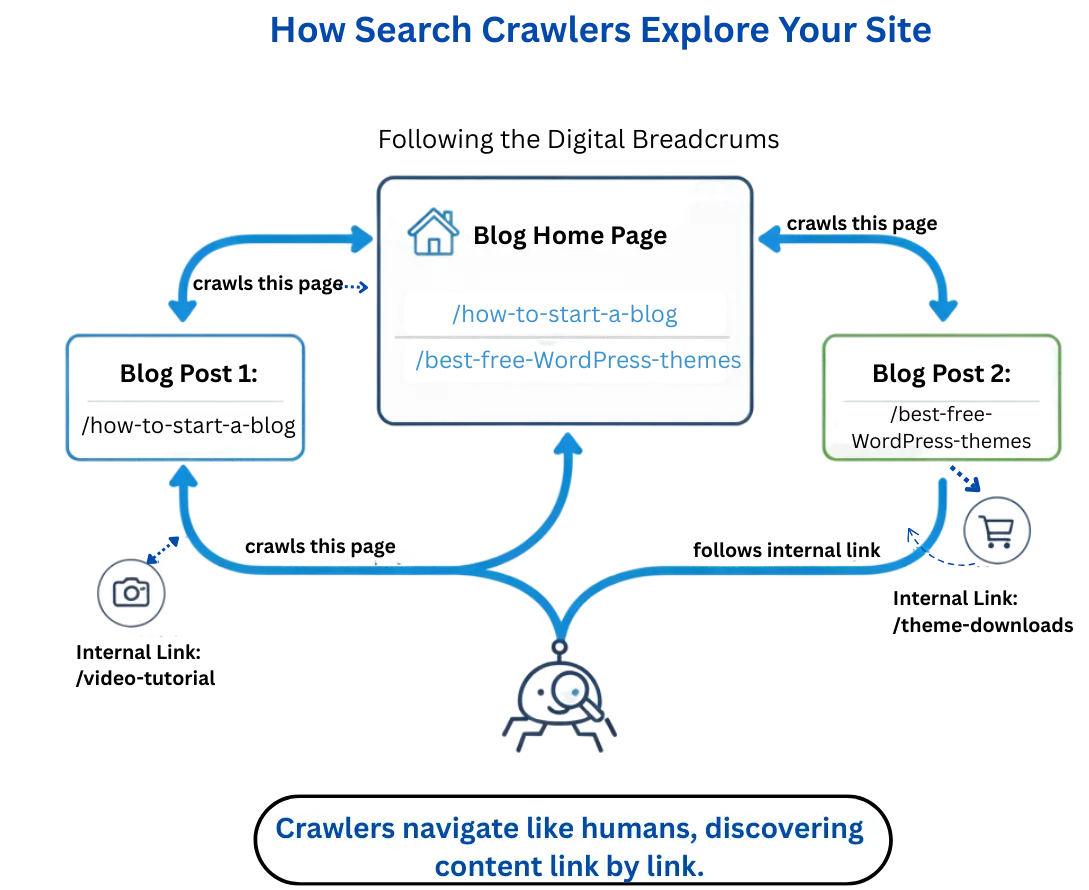
Suppose a crawler comes to your blog home page. It finds links to your other blog pages such as:
/how-to-start-a-blog
/best-free-WordPress-themes
It will click on those links (just like a human would), crawl those pages, and then move to any links there.
Why Do Crawlers Matter?
1. They Help Search Engines Discover Your Content
Suppose you've just released a fresh blog post or created a new website. You'd like folks to be able to see it, correct? Well, if a crawler doesn't discover and read your page, search engines won't even be aware it's there. Which means:
1) Your site will not appear in Google search
2) No one will notice your content unless they happen to know your URL.
3) Crawlers are like internet scouts. If they don't exist, your content remains a secret.
2. They Keep Search Results Up to Date
The internet is constantly changing, new pages emerge, old ones disappear, and others are modified. Crawlers visit sites regularly in order to observe what's new or has been changed. That way, search engines can:
1) Show fresh, accurate results
2) Delete old or broken pages
3) Understand what's currently relevant
Without crawlers, search engines would be presenting you with information from several months or even years ago.
3. They Impact Your SEO
In case you want traffic from search engines (a.k.a. Search Engine Optimization or SEO), crawlers are important. Stuff such as:
i) Page speed
iii) Site structure
iv) Internal linking
Robots.txt and sitemap.xml usage…influence how a crawler can browse your site easily. And that influences how well you rank for search terms.
If crawlers have trouble interpreting or accessing your content, your SEO suffers.
4. They’re Your First Audience
Before humans view your content in search, crawlers do. Imagine it this way:
Humans visit your site after crawlers visit your site. So, you'll want to ensure your website is friendly, not only to visitors, but to crawlers too.
In Short: Why Crawlers Matter?
Reason | Why It Matters |
|---|---|
Discovery | They help search engines find your site |
Freshness | They keep search results current |
Indexing | They add your pages to the searchable database |
SEO | A crawl-friendly site ranks better |
First Audience | They “see” your content before anyone else |
Final Thoughts
Crawlers are the silent workers behind all your online searches. They explore the web, gather information, and assist search engines in comprehending the World Wide Web. Without crawler, search engines would be unaware of what information is out there and your favorite site may never appear in search results.
If you're studying SEO or simply interested in how Google functions, learning about crawlers is a wonderful place to start. Keep your site crawl-friendly, and you're off to a good start towards increased search visibility.
Frequently Asked Questions (FAQs)
What's the difference between crawling, indexing, and ranking?
Crawling basically means that search engines find your pages.
Indexing is where they store and understand your content, and
Ranking is where your page actually shows up in search results.
They're three separate steps, but they all work together.
Do crawlers visit every single page on the internet?
No, not even close. Some pages are blocked or hidden behind logins; others simply are not important enough to get crawled often. Crawlers focus their energy on what's accessible and what appears to be valuable.
How can I tell if Google has crawled my site?
The easiest way to do this is through Google Search Console, which will show you which pages Google has crawled and indexed. You can also Google “site:yourwebsite.com” to see what’s already showing up.
How long does it generally take for Google to crawl a new page?
There is no fixed time. Sometimes it happens within hours; other times it takes a few weeks. It really depends on your website's authority, how often you update it, and how well it is structured.
Why might a crawler be unable to access my website?
A few things can stand in their way, including an incorrect setting up robots.txt file, slow website speed, broken links, server problems, or a messy site structure. Fixing these usually helps the crawlers enter without trouble.
How can I make my website easier for the crawlers to go through?
A crawl-friendly site is quick, well-organized, mobile-friendly, and full of internal links. Adding a sitemap and fixing broken links will also make a big difference.
What is a crawl budget and why does it matter?
Crawl budget refers to the number of pages a search engine crawler is willing to crawl on your site. Optimizing it ensures crawlers discover your most important pages.


4.9/5 Ratings!

Share this article